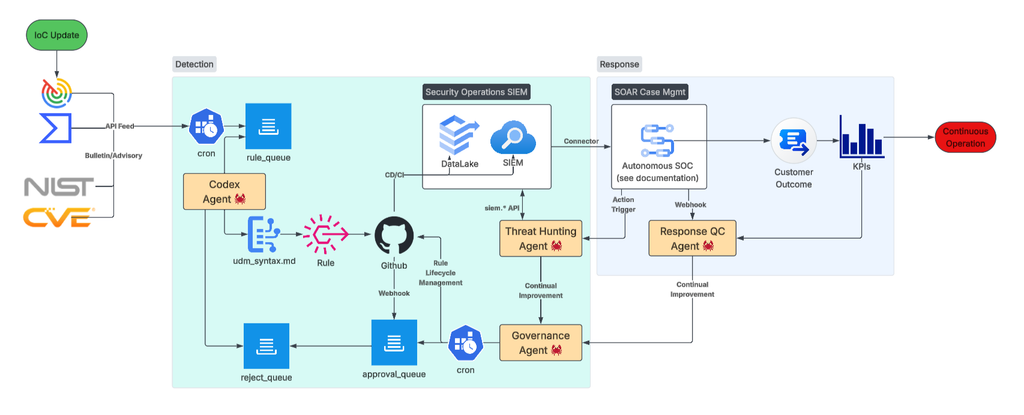
The concern this page answers: How do we keep our detection capabilities up-to-date?
New threats and IoCs are surfaced all the time.
Engineering detection capabilities need to be continuously reviewed and updated. .
Four gates and one soak reads like bureaucracy.
The objection is fair on its face. Indeed, every gate is a place work can stall, and detection engineering competes with attackers who do not hold change advisory boards.
The answer is not fewer gates. It is that most of what used to make a gate expensive was clerical, and clerical work is exactly what agents absorb.
What each gate actually costs now
| Gate | Historically | Now |
|---|---|---|
| 1. Engineering Validation | Read the standard, hand-check identifiers and field mappings, hope you did not miss a required section | validate_rule.py, about a second. Reads naming-registry.yaml, so it fails an unallocated family or band by name and tells you which one |
| 2. Independent Review | Schedule a peer, wait for a slot, get inconsistent depth depending on who was free | /raas-review against a published six-dimension rubric, on demand, same rubric every time |
| Soak stages 1 and 2 | A calendar commitment nobody owned, often skipped under pressure | A waiting period, not a meeting. The rule runs with alerting off while you do other work. Evidence accumulates in the package working tree |
| 3. CAB | Judgement | Still judgement. Unchanged |
| 4. Alerting change request | Frequently bundled into deployment and never explicitly decided | Still judgement, now explicit and per environment |
Two of six steps need a human, and they are the two that commit the organisation to a real cost:
absorbing alert volume, and pointing alerts at an analyst queue.
Where the gates stopped being paperwork
The governance file is the mechanism. Everything a gate needs to know is a field, so the tooling can check it instead of a person remembering to:
detection.data_sources[].telemetry_verified— Phase 0’s telemetry check. An unverified required source is recorded and warned on, and travels with the rule to review and CAB. It does not block.governance.soak.stage1_cw_security.days— the seven-day floor.promote_rule.pyrefuses--to alertbelow it, and refuses outright iflogic_changed_during_windowis set, because the clock restarts when logic changes.governance.alerting_cr.<environment>.cr_ref— Gate 4. Two environments, two decisions, two change requests. Enabling alerting on cw-security does not authorise it on customer tenants.
None of that is new policy. It is the same policy, moved from prose a person had to remember into fields a script can enforce — which is what makes it cheap to comply with and hard to skip by accident.
What the agents do
| Agent | Purpose |
|---|---|
mdr-governance-agent | Aligns |
mdr-rule-engineer | Takes a detection intent through Phases 0–3: telemetry feasibility, identifier assignment, prior-art search across the corpora, and the full four-part operational package. Stops at authoring. |
/rule-review | Gate 2, against the published rubric. Never on content it authored — an agent that writes and then scores its own rule has produced two opinions from one source, not a gate. |
| Hunting agents (next phase) | Continuous retrohunt over deployed content, feeding observed volume and false-positive drift back into the tuning cycle |
Both shipped agents run out of the repository, so a contributor gets them by cloning it. Point Claude Code or Codex at the folder root and ask.
What agents are not allowed to do
The separation of duties is the entire reason the gates mean anything, so it is enforced rather than encouraged:
An agent never enables alerting, never reviews its own work at Gate 2, never sets CWRuleSetID, never shortens a soak, and never deploys. It prepares content and evidence; a human with platform authorisation decides and deploys.
An agent that could approve its own detection into an analyst queue would not be an efficiency gain.
Why this makes the throughput argument
Speed came from removing clerical latency
- A rule that fails Gate 1 fails in a second, not after a review cycle. Bad submissions stop consuming reviewer attention.
- Prior-art search is cheap enough to actually do, so “adopt the legacy rule” beats “author a near-duplicate” — which is where most of the real coverage gain is. We run 481 production rules that predate this framework; bringing one into governance is worth more than writing its twin.
- Review depth is consistent, so a PASS means the same thing regardless of who was available.
- The soak is the only genuinely slow step, and it is slow on purpose. Seven days of measured volume is what stops an uncharacterised false-positive rate landing on the analyst queue — the failure mode that gets rules disabled instead of tuned, which costs far more than seven days.