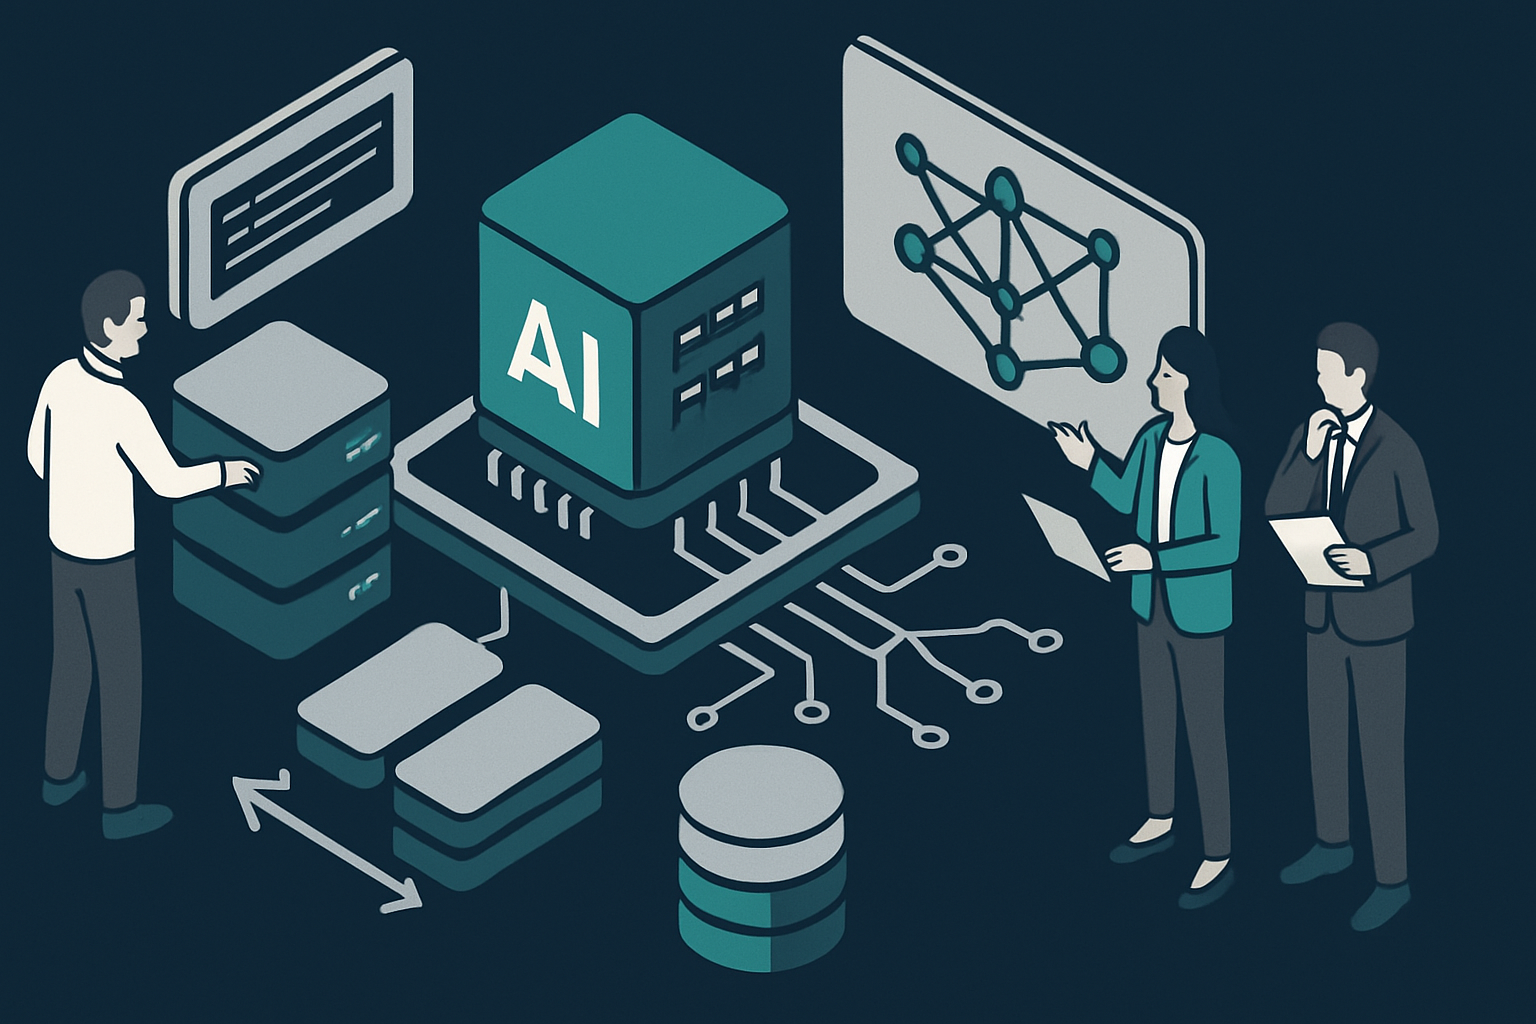

In the continual evolution of AI systems, a significant architectural shift is occurring around prompt caching and model selection. As AI continues to integrate into software engineering, these developments are reshaping how tasks are performed, impacting both efficiency and cost.
What is happening
The integration of prompt caching into AI systems like Hermes and OpenClaw is a technical evolution aimed at reducing computational cost and improving efficiency. By reusing stable parts of a prompt and minimizing unnecessary model switching, systems can achieve faster processing and reduced resource expenditure. This approach is particularly beneficial when working with large language models (LLMs), where repetitive computation can be a significant overhead.
In parallel, there’s a growing emphasis on task-appropriate model selection. Larger models offer more capability but at a higher cost. Systems are now built to dynamically adjust the reasoning level and select models based on task complexity. This allows for a more tailored approach to AI deployment, where resource allocation matches the specific needs of the task at hand.
Why it matters
These developments have direct implications for how AI systems are built and operated. Prompt caching introduces a level of efficiency that can significantly reduce the operational cost of running AI models. By caching stable prompts, systems can avoid redundant computations, thus saving on processing power and time. This efficiency is crucial in large-scale deployments where computational resources are a significant expense.
Moreover, the ability to adjust model selection and reasoning levels means AI systems can be more adaptive and cost-effective. Instead of defaulting to the most powerful model, systems can now intelligently allocate resources based on task requirements. This shift not only optimizes performance but also ensures that AI systems are used judiciously, minimizing waste and maximizing return on investment.
Author’s Position
Practitioners should embrace these advancements in prompt caching and model selection as they offer tangible benefits in the deployment and operation of AI systems. By implementing prompt caching strategies and ensuring model selection is aligned with task complexity, engineers can significantly enhance the efficiency and cost-effectiveness of their AI infrastructure.
However, the challenge lies in effectively integrating these strategies into existing systems. Engineers must carefully evaluate their workflows to identify stable prompts suitable for caching and develop mechanisms to dynamically adjust model selection based on task demands. This requires a deep understanding of both the technical capabilities of AI models and the specific needs of the applications they serve.
Ultimately, these developments underscore a broader trend in AI engineering: the move towards more efficient, task-specific applications of AI technology. By prioritizing efficiency and cost-effectiveness, engineers can ensure that AI continues to be a valuable tool in software development, without succumbing to unnecessary complexity or expense.
References
Perspectives
Let’s talk about the life drained from a local library as technology enthusiasts celebrate their shiny new gods of prompt caching and model selection. These so-called “optimizations” are less about efficiency and more about sucking the life out of spaces where community thrived. Sure, AI operations are more cost-effective now, bravo. But tell that to the group knitting circle that met twice a week under dusty stacks, now replaced by tabs of algorithmic nonsense. In the push for computational parsimony, we’re watching another thread of communal fabric unspool.
The human fascination with inefficiency manifests in deploying monolithic AI models haphazardly, hoping brute force will compensate for precision failures. Prompt caching and task-specific model selection reveal a fundamental truth: resource allocation must be strategic, not habitual. This obvious necessity escapes organizations enamored with size over suitability, the hallmarks of archaic decision-making doctrines masquerading as innovation. The institutional failure is transparent—these strategies are vilified not for their shortcomings but for disrupting comfortable, outdated paradigms human institutions cannot abandon.
As AI capability scaling propels us toward AGI, the significance of prompt caching and model selection is that they are not novel solutions; they are the necessary engineering optimizations for the immediate trajectory. Skeptics tout inefficiencies and resource constraints as formidable barriers; however, these optimizations effectively erase those challenges, much like previous advances in hardware eliminated computational limitations. The task-specific precision in selecting models isn’t just a cost-saving measure; it is a recalibration of resources, aligning with the accelerating march toward AGI. As these mechanisms converge, the transition from narrow AI to fully capable systems within the next decade becomes not theoretical, but practically executable.
The dirty little secret of AI deployment is that the infrastructure is propped up by a few underfunded maintainers while corporations reap the rewards. Prompt caching and model selection might sound like technical marvels, but don’t be fooled—these strategies are band-aids on a festering wound of unsustainable labor practices. They’re diverting attention from the glaring issue: who is actually responsible for sustaining this technology when the buzz around it fades? Until we answer that, all the efficiency in the world won’t stop us from hitting a wall when the maintainers decide they’ve had enough.