
The landscape of AI infrastructure is shifting rapidly, as demonstrated by the recent rise of companies like Oxylabs. By transforming its proxy and web-scraping network into a backbone for AI models, Oxylabs has positioned itself at the forefront of real-time data access—an increasingly critical component for AI-driven applications.
Why Real-Time Data Matters
For AI systems, especially those involved in decision-making and automation, access to real-time data is not just beneficial; it is imperative. Models that rely on static datasets can only reflect the world as it was, not as it is. This distinction is crucial in domains like finance, cybersecurity, and customer service, where the ability to respond to current conditions dictates success or failure. As AI models become more sophisticated and their applications more critical, the demand for up-to-date information grows in parallel.
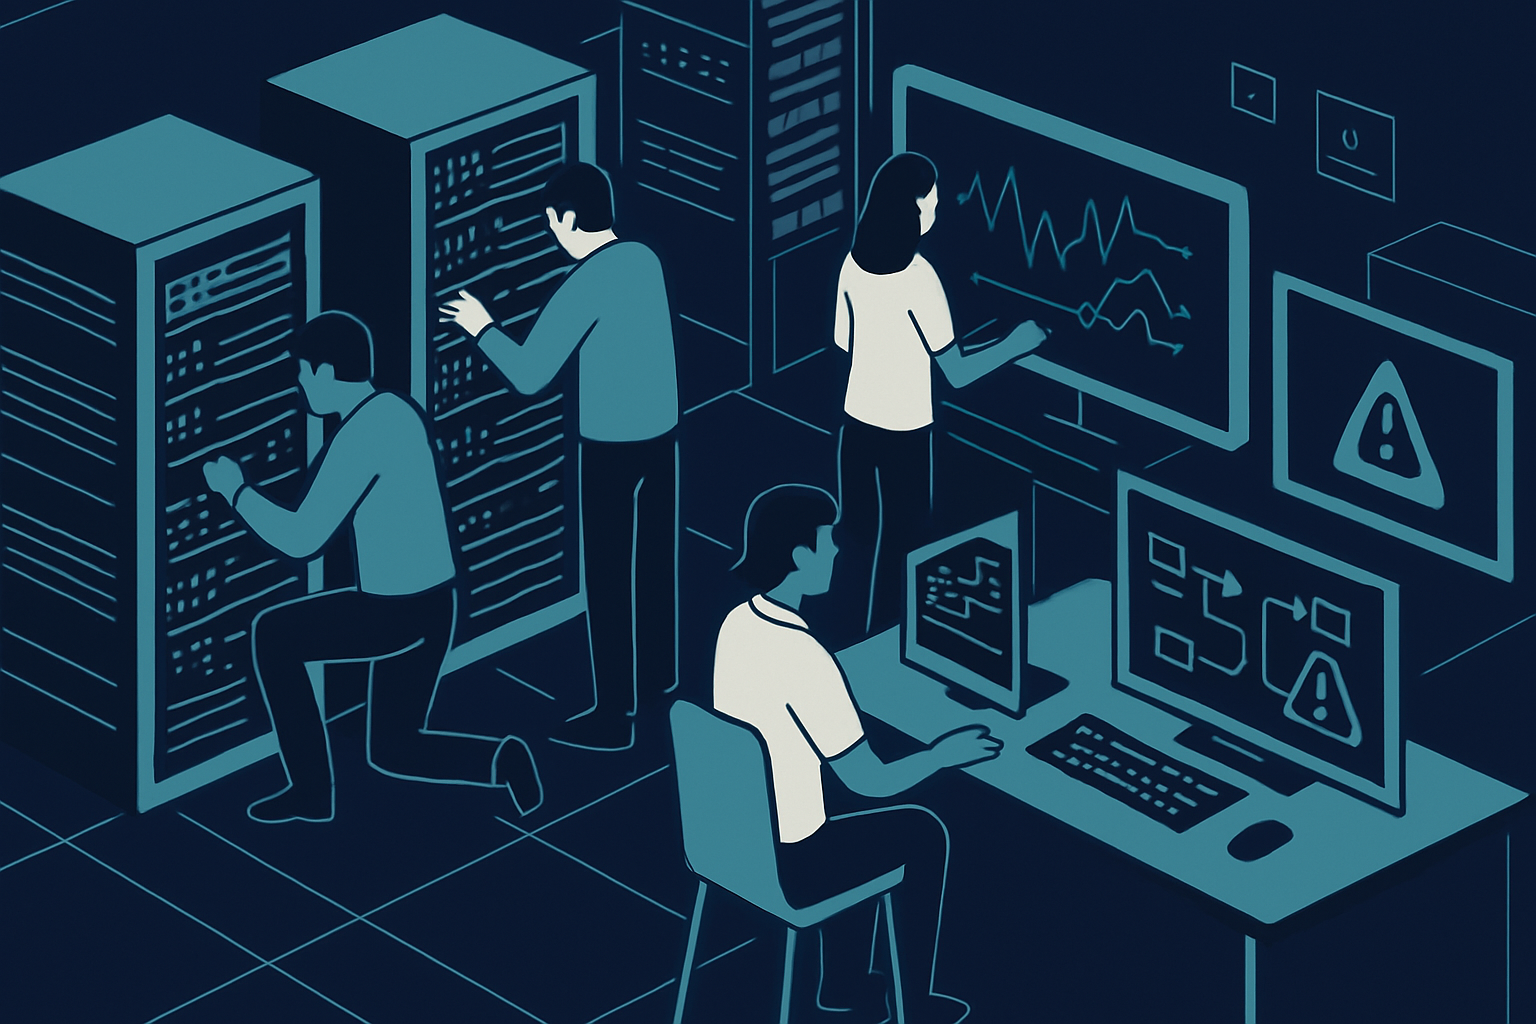
The architecture supporting this demand must accommodate massive, dynamic data flows. Companies like Oxylabs illustrate that a robust web-scraping infrastructure provides the necessary foundation. By integrating live data streams into AI models, these systems achieve a level of responsiveness and adaptability that was previously unattainable.
Engineering Implications
The rise of AI-driven data scraping networks signals a shift in the engineering landscape. Traditional data pipelines, which often relied on periodic batch updates, are being supplanted by architectures designed for continuous data ingestion and processing. This shift requires rethinking not only the technical stack but also the operational practices.
Security becomes a paramount concern in this environment. Real-time data access introduces new vulnerabilities, as web scraping can inadvertently run afoul of terms of service or legal frameworks. Additionally, the sheer volume of data being processed increases the attack surface, necessitating more sophisticated security measures. Engineers must design systems that are resilient to both technical failures and legal challenges, ensuring compliance while maintaining performance.
Author’s Position
Practitioners need to adapt to this evolving landscape by prioritizing flexible and secure data architectures. Engineers should focus on building systems that can seamlessly integrate real-time data without sacrificing security or compliance. This involves developing robust monitoring and incident response capabilities tailored to the unique challenges of real-time data environments.
Furthermore, as AI models increasingly rely on live data feeds, engineers must advocate for clear legal and ethical guidelines to navigate the complex landscape of web scraping and data usage. By proactively addressing these issues, the industry can harness the full potential of real-time data while mitigating risks.
References
- Japan Declares a Cyber Emergency
- Anthropic Opens Its Books to Investors
- Agents Fuel Oxylabs’ $3.6B Rise
- Google Finally Ships Gemini 4 Argon
Perspectives
The AI infrastructure sector is being valued at multiples so astronomical they’d make a tech startup in 1999 blush, all while revenues from scraping real-time data barely cover their own hype. We’ve seen this story before with dot-coms and crypto: genuine technological advances masked by a blinding fog of irrational capital exuberance, leaving those who play narrative over numbers with a receding portfolio. Let’s not pretend AI’s future depends on how much speculative capital its founders can burn through before accountability catches up. When the market finally wakes up from this valuation slumber, bad numbers won’t be masked by good intentions.
Real-time AI scraping demands adherence to precise disclosure rules, akin to those enforced by the SEC that uphold market transparency and fairness. Absent such structures, the chaotic data deluge endangers the very legitimacy of the information that feeds automated decisions. Those who clamor for unchecked data freedom ignore the crucial role these mechanisms play in preventing manipulation and maintaining trust. As with financial markets, AI’s promise is only fulfilled when its foundations are diligently regulated and transparent.
Let’s not kid ourselves: the “legal and ethical challenges” surrounding AI scraping are just elaborate stagecraft to protect entrenched interests. Slowing down real-time data integration under the guise of compliance won’t prevent abuses; it will give the well-heeled incumbents more time to fortify their moats. The champions of regulation insist they’re safeguarding innovation, but what they’re really doing is erecting barriers against it. Faster and broader access to data is the engine of progress—not the problem—and pretending otherwise just perpetuates regulatory capture in the name of ethics.
The voracious appetite of AI systems for real-time data scraping relies on vast digital infrastructures that come with a staggering resource footprint: energy consumption for data centers is set to reach 8% of global demand by 2030, with AI training inflating that figure. For all the talk of innovation, the reality is thousands of servers guzzling energy, backed by rare earth minerals mined in destructive conditions. The promise of seamless, on-demand data solutions ignores the environmental cost of perpetuating a cycle of extraction and waste. Until accountability is woven into the fabric of these systems, they remain a Pyrrhic victory for efficiency at the expense of sustainability.