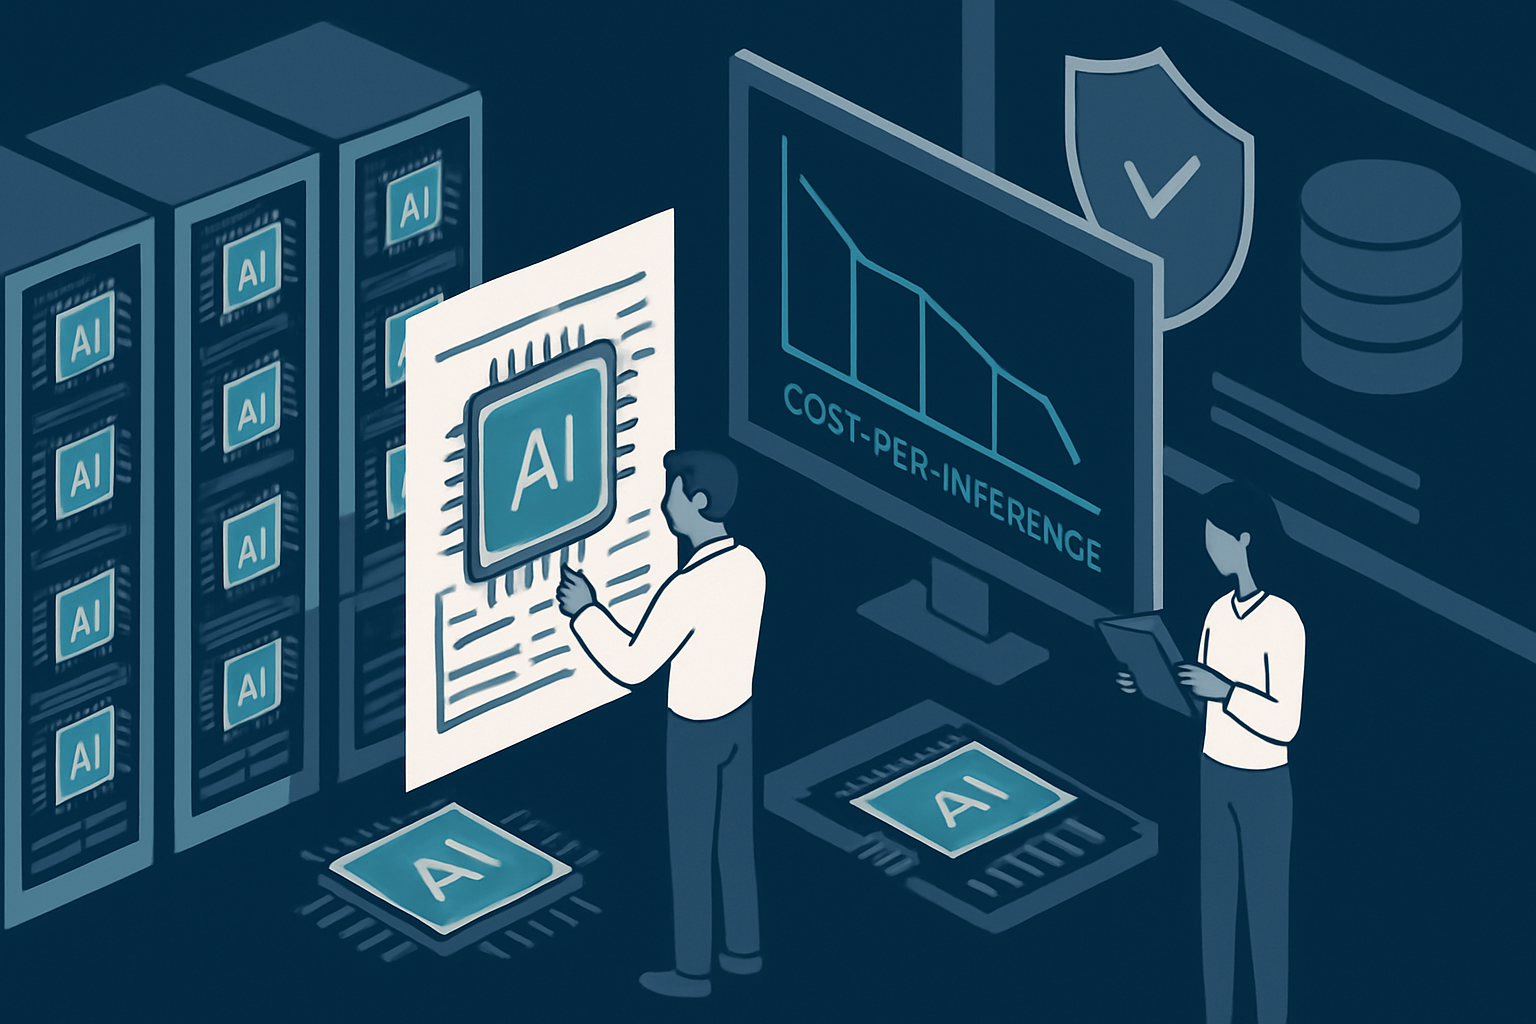

The recent developments in AI infrastructure, particularly the funding and technological advancements discussed in the sources, point to a significant shift in how AI models are deployed and operated. Positron AI’s substantial $875 million funding to develop inference chips and DeepSeek’s release of the V4.1-Flash model are emblematic of the industry’s focus on optimizing the trade-offs between performance and cost.
What is happening
Positron AI is betting on cutting inference costs by swapping high-bandwidth memory (HBM) for consumer-grade DRAM in their chip designs. Meanwhile, DeepSeek’s V4.1-Flash demonstrates an ability to significantly reduce the memory requirements needed for AI models, using less HBM and SSD storage compared to its predecessors. These technological strides are driven by the need to make large-scale AI systems more economically viable while maintaining competitive performance metrics.
Why it matters
The implications for system architects and engineers are profound. The shift towards more cost-effective memory solutions for inference chips could democratize access to powerful AI capabilities, reducing the barriers for smaller players to enter the market. However, this also raises questions about the trade-offs being made in terms of latency, throughput, and potentially increased wear on cheaper memory components.
Moreover, DeepSeek’s reduction in memory usage for its V4.1-Flash model could influence how models are trained and deployed across different infrastructures, from cloud to edge. This could lead to a reevaluation of existing architectures and necessitate changes in how data pipelines are constructed and optimized.
Author’s Position
Practitioners need to approach these developments with a critical eye. While the promise of reduced costs is attractive, it’s crucial to scrutinize the long-term impacts on system reliability and performance. Engineers should investigate the detailed specifications of these new chips and models, evaluating whether the trade-offs align with their operational goals and risk tolerances.
Furthermore, the ethical and security considerations cannot be ignored. The accusations against DeepSeek for potentially misusing user data highlight the importance of transparency and trust in AI operations. As such, practitioners should advocate for robust governance frameworks and ensure compliance with evolving regulatory landscapes to protect user data integrity and privacy.
References
- Chinese Labs Accused of Relaying Queries to Claude
- Healthcare AI Hits a Regulatory Wall
- Positron Raises $875M for Inference Chips
- DeepSeek V4.1-Flash Slashes Memory Needs
Perspectives
The rush to cut costs with AI inference at scale is driven by institutional incentives prioritizing immediate profitability over the rigorous performance validation we know is crucial, creating yet another cycle of poorly vetted technological bandwagons. Positron’s DRAM-based chips and DeepSeek’s memory-efficient models present supposedly innovative solutions, but there’s no escaping the fact that the focus on cheapness over reliability will inevitably lead to missteps — steps hampered further by an academic and industrial review process more obsessed with novelty than with sound, reproducible results. We’ve seen it time and again: when funding and publishing rewards are designed to chase trends, the result isn’t robust, scalable technology; instead, we yield an endless series of revisions once the initial excitement fades. If these cost-cutting measures are genuinely worth their salt, it’s time the responsible institutions realign their incentives to support comprehensive and transparent evaluation methodologies — rather than becoming enablers of yet another short-sighted chase for savings.
In cognitive science, decision-making thrives on a surplus of options, yet these companies seem ready to burn through human faculties to save a buck on AI inference. Positron and DeepSeek are like those illusionist entrepreneurs selling ‘efficiency’ with new tech while skipping over the real price: comprehensibility and control. The dark pattern of prioritizing penny-pinching over the transparent human-AI interaction is a design flaw as reckless as it is routine. And in case you’re wondering if those scurrying about with memory-efficient models have thought about the cognitive tax they’re imposing — they haven’t.
Positron’s and DeepSeek’s recent advancements in AI inference technology highlight our industry’s unwavering commitment to maximizing operational efficiencies while generating dynamic opportunities for stakeholder engagement. Concerns regarding performance trade-offs and governance implications have been noted; however, they are firmly counterbalanced by the robust cost-reduction frameworks and innovation synergies that these advancements catalyze. It is essential to underscore that the deployment of DRAM-based chips and memory-efficient models is not merely an exercise in economizing resources, but a strategic alignment with the long-term vision for sustainable technology ecosystems. By leveraging these developments, we are poised to redefine operational benchmarks and reinforce our foundational commitment to transformative scalability and performance resilience.
Positron’s DRAM-based chips and DeepSeek’s memory-efficient models may look like shrewd cost-cutting at first, but let’s not kid ourselves about the actual stakes: data collection is still data collection, no matter how efficiently it is processed. The reduction in computational expense conceals an underlying danger—the cheap ubiquity of data retention and inference at scale. A lower financial barrier to AI inference does not come without a societal cost: the entrenchment of surveillance infrastructure that adapts more swiftly than any policy can hope to regulate. The real agenda isn’t about efficiency, it’s about the eventual power dynamics and misuse potential of these “innovations” once the systems have outgrown their initial justification.